AI
PrismML Ships Ternary Bonsai 2 Models Built for Phones, From 0.43GB Up to 2GB
The Caltech-rooted lab released 2B, 4B and 9B Qwen3.5-based ternary weights on Oct. 15, claiming up to 120 tokens per second on an iPhone 18 Pro Max and Apache 2.0 downloads via llama.cpp and MLX.
Pasadena, Calif. · Jordan Hale, AI · Oct 16 2026
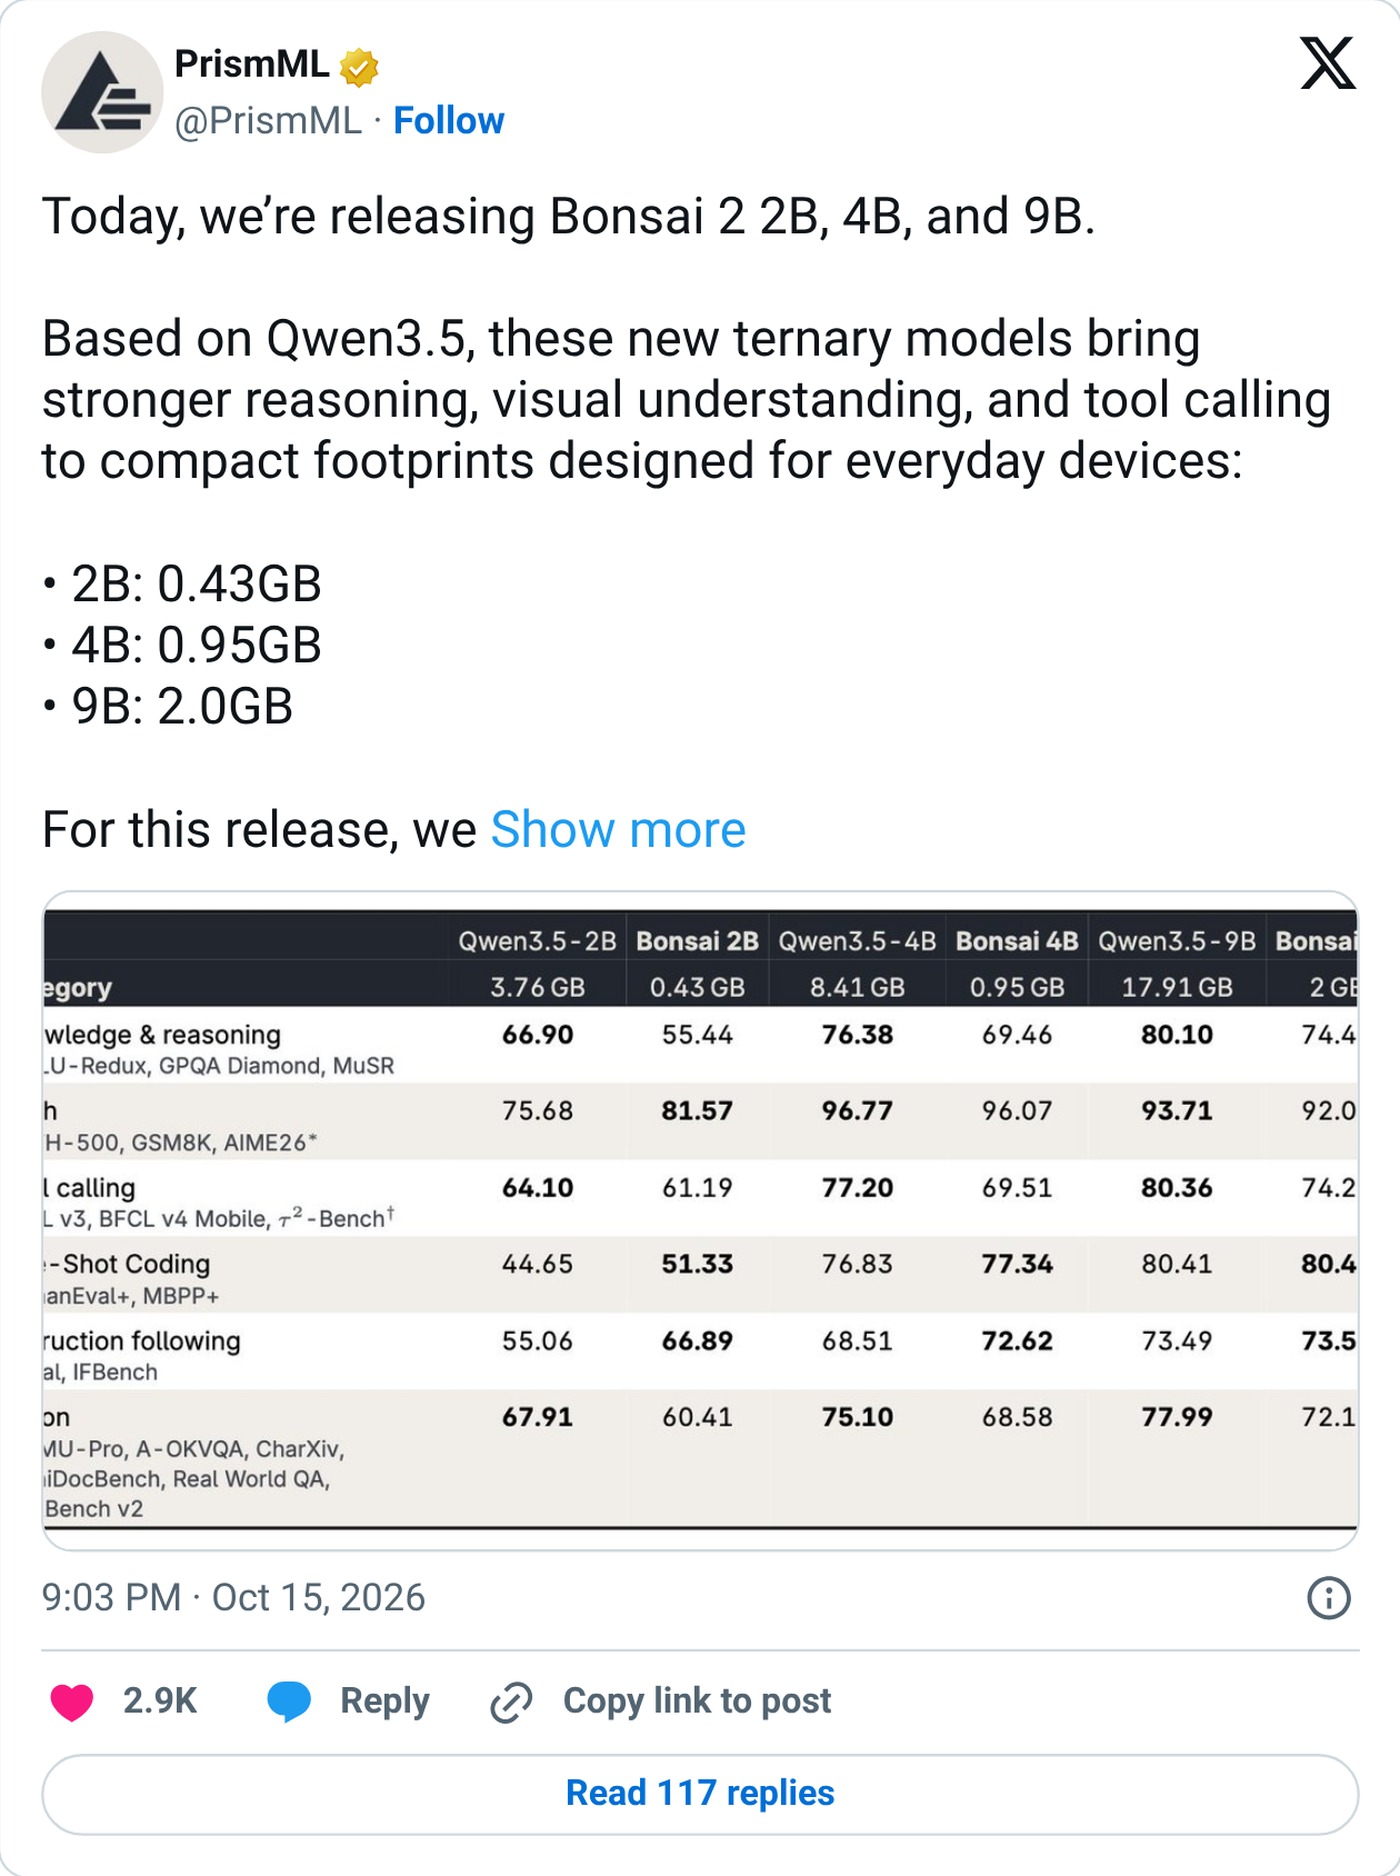
PASADENA, Calif. - PrismML released Ternary Bonsai 2 in 2B, 4B and 9B sizes on Oct. 15, expanding its Bonsai 2 family beyond the earlier 27B cut with footprints aimed at phones, PCs and wearables. The new models use ternary weights of -1, 0 and +1 and shrink to about 0.43GB, 0.95GB and 2GB, the company said, more than nine times smaller than full-precision counterparts based on Qwen3.5.
The pitch is local agents that can reason, read images and call tools without shipping every prompt to the cloud. PrismML published retention scores across 19 benchmarks spanning tool use, math, instruction following, coding, knowledge and vision. On mobile-focused BFCL v4, the 4B and 9B models retain more than 95 percent of the matching Qwen3.5 baselines in the lab’s table.
Speed claims are what phone buyers will notice first. PrismML says Bonsai 2 2B reaches up to 120 tokens per second on an iPhone 18 Pro Max, while the 9B hits about 34 tokens per second. On Apple silicon desktops, the lab cites up to 310 tokens per second for the 2B and 179 for the 9B on M5-class hardware, with up to 5x throughput and 3x energy efficiency versus full-precision twins on RTX 4090 and M5 Pro class machines.
 Photo: PrismML
Weights are Apache 2.0. NVIDIA GPUs are supported through llama.cpp, and Apple Mac, iPhone and iPad devices through MLX. PrismML also pointed developers to Darkbloom for a hosted Bonsai 2 9B trial with a limited free-token grant for early users. A whitepaper covers compression and evaluation methods.
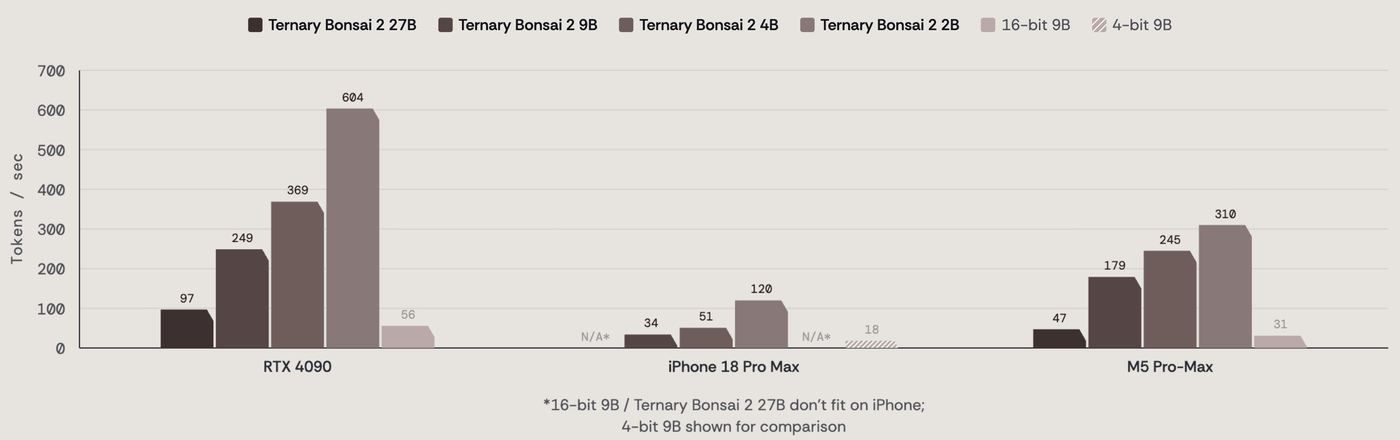 Photo: PrismML
The release sits next to a busy week for on-device AI PCs. NVIDIA’s RTX Spark laptops, including ASUS ProArt machines now on sale, target larger local models with tens of gigabytes of unified memory. Bonsai 2 is the opposite end of the spectrum: models small enough for a pocket device that still claim agentic tool calling. Techtember’s earlier coverage of RTX Spark PC availability tracks that high-memory path.
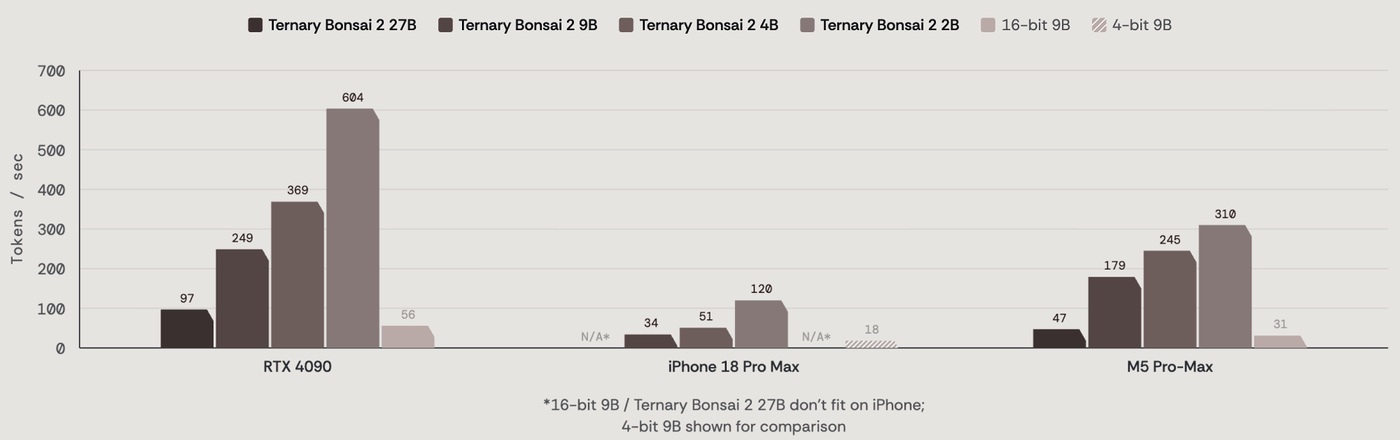 Photo: PrismML / press coverage
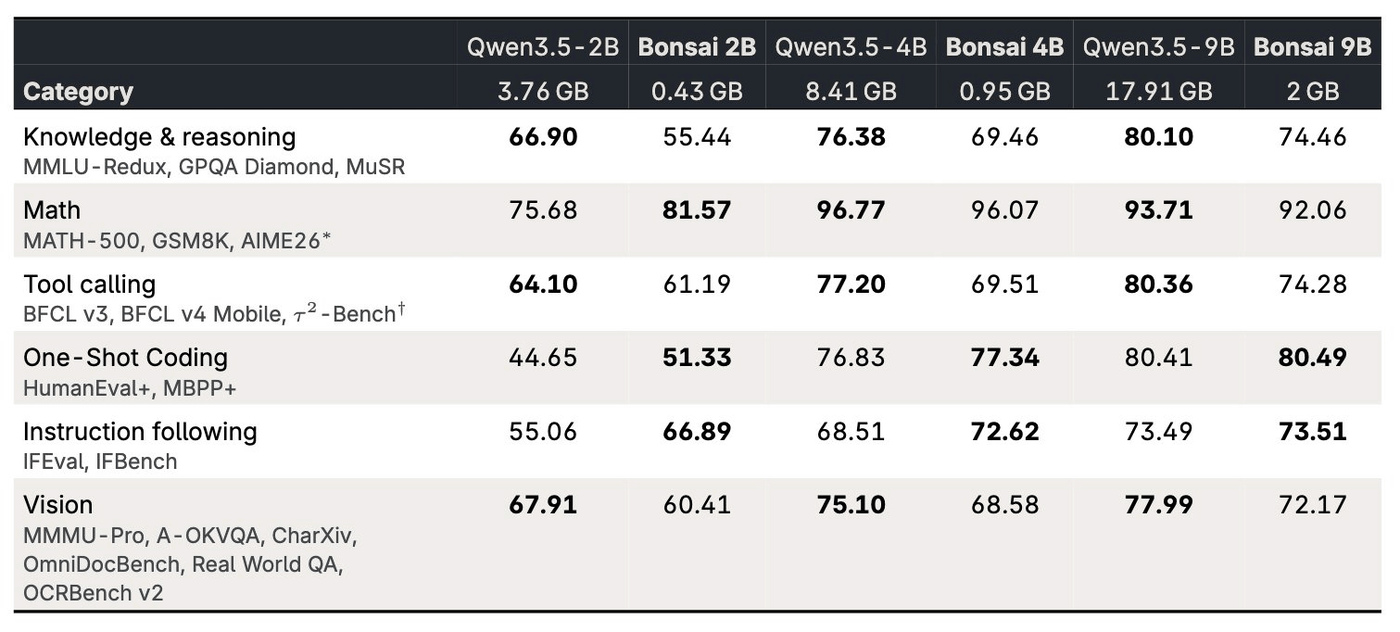 Photo: PrismML / press coverage
@PrismML’s Oct. 15 post framed the family as everyday-device agents rather than lab curiosities. Independent developers were already posting MLX fine-tune experiments and local chat integrations within a day. The open question is whether ternary quality holds up once users leave the benchmark sheet and live inside Messaging, camera and file workflows on mid-range phones.
*Video: @PrismML on X, Oct. 15, 2026*