AI
Mistral Releases Le Chonk's Weights, and a 2-Bit Version Runs on One M3 Ultra Mac
The 1-trillion-parameter Mistral Large 4 is now free to download from Hugging Face under a modified MIT license, with lower prices, three reasoning modes and a cybersecurity pitch aimed at defenders.
Paris · Jordan Hale, AI · Oct 30 2026
PARIS - Mistral AI on Thursday released the weights of Mistral Large 4, the 1-trillion-parameter model it nicknamed “Le Chonk,” making good on the promise it made when the model entered public preview on Oct. 6. Anyone can now download it from Hugging Face, and Mistral says the released model is an improved version, trained with three more weeks of reinforcement learning since the preview.
“Today, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity,” the company wrote. Chief executive Arthur Mensch put it more briefly on X: “Good progress in the last few weeks ! And now the weights.”
 Screenshot: @arthurmensch on X
The model is a mixture of experts, which means only a slice of it runs for each token. Mistral’s documentation lists 1.05 trillion total parameters and 52 billion active ones, a 1-million-token context window and a 1.6 billion-parameter vision encoder for image input. It ships in two official formats, FP8 and NVFP4, and Hugging Face added day-one support in its Transformers library, vLLM and llama.cpp.
The part hobbyists will notice is how small it can get. In a Hugging Face blog post, the company’s engineers said 2-bit quantized versions run on a single Apple Silicon Ultra machine with 512GB of unified memory. On one M3 Ultra, they measured prompt processing of about 90 tokens per second and generation of 15 tokens per second. On four Nvidia RTX 6000 Pro cards, a 2-bit build handled an 800,000-token context, though generation slowed to 3 tokens per second at long lengths. Full-precision serving still calls for a server, and Hugging Face’s ready-made recipe uses eight Nvidia H200 GPUs.
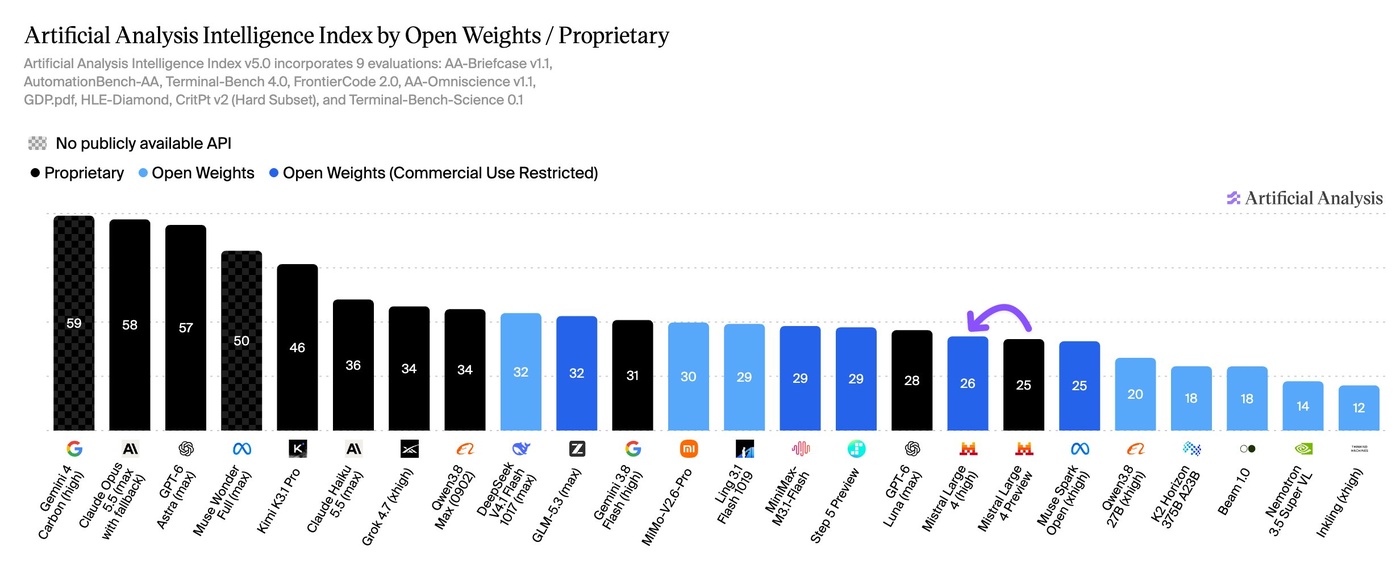 Image: Artificial Analysis
Independent testers rate it as the best open model built outside China, narrowly. Artificial Analysis said Mistral Large 4 scores 26 on its Intelligence Index, one point ahead of Meta’s Muse Spark Open, the top U.S.-developed open model, and six points behind the Chinese leaders DeepSeek V4.1 Flash and GLM-5.3. The firm measured 39% fewer output tokens per task than the preview used and a hallucination rate of 28%, down from 41%. On its Cyber Index the model scored 51, third among open models.
Mistral’s own pitch leans on coding and defense. It said the model leads open-weight rivals on Cognition’s FrontierCode 2.0 with 19.7% and on Terminal-Bench 4.0 with 41%, a 13-point gain over the preview. It also said the model refused 96.6% of malicious cyber requests drawn from the JailbreakBench, StrongREJECT and AgentHarm tests, the highest rate it measured among open models. The company flagged a risk as well. After watching live traffic since the preview, it said it saw “a potential for uplift to conduct real attacks” and is tightening its guardrails. A more permissive variant for penetration testing and red-teaming goes only to vetted partners such as Orange Cyberdefense.
 Image: Mistral AI
The license is a modified MIT license that Mistral calls the Mistral Ecosystem Open-Weight license. The model is free to use, modify, fine-tune and sell, with one condition: companies running a model-as-a-service business need a separate commercial license from Mistral. API pricing also fell to $0.70 per million input tokens and $2.10 per million output tokens, about half the preview’s rate, according to Artificial Analysis. The model now offers low, medium and high reasoning modes, and Microsoft said it is the first cloud provider to offer it, through Microsoft Foundry.
*Video: Hugging Face / YouTube*Mistral said Large 4 will serve as the foundation for a new generation of smaller, specialized models, and that a full technical report is coming soon.